
|
 |

|
|
|
|
|
|
Silence is a source of great strength, Lao Tzu
AI-powered tools have transformed image and video creation in 2025, democratizing high-quality content production for artists, marketers, educators, and hobbyists. These advancements leverage sophisticated models trained on vast datasets to generate visuals from text prompts, edit existing media, and even animate static images.
Before diving into generative AI, high-quality stock assets remain essential for hybrid workflows — combining free media with AI editing saves time and reduces costs.
Infographics transform data into engaging visuals, and AI tools in 2025 automate design, layout, and content suggestions.
Infografix fast-tracks you through the design process, using simple text prompts to instantly create infographics for you to share or use wherever you want; free tier with premium exports.
Napkin turns your text into visuals so sharing your ideas is quick and effective.
Flux AI: A high-performance AI image generation model from xAI, designed for creating detailed, customizable visuals from text prompts. Ideal for artists and designers.
PicLumen. Convert text into images effortlessly with PicLumen’s free AI image generator.
Stable Diffusion: An open-source AI model for generating high-quality images from text descriptions. It’s widely used for creative projects and supports fine-tuning for specific styles.
Google Gemini Image (Nano Banana Pro) is an amazing text-to-image and image-editing model.
Others: Midjourney, DALL-E (via ChatGPT), Ideogram, and Grox Image (xAI).
FLUX AI refers to a series of cutting-edge text-to-image models developed by Black Forest Labs, known for their exceptional image quality, detail, and prompt understanding. Flux AI’s local setup enables offline generation, avoiding cloud costs.
flux1-dev-bnb-nf4.safetensors, and move it to D:\StableDiffusion (your path to AI StabilityMatrix) + \Data\Models\StableDiffusion\ae.safetensors, and place it in D:\StableDiffusion (your path to AI StabilityMatrix) + Data\Models\VAE.local URL: http://127.0.0.1:7860
flux (FLUX UI). Go to the Checkpoint dropdown, select flux1-dev-bnb-nf4.safetensors. Go to the VAE tab, select ae.safetensors.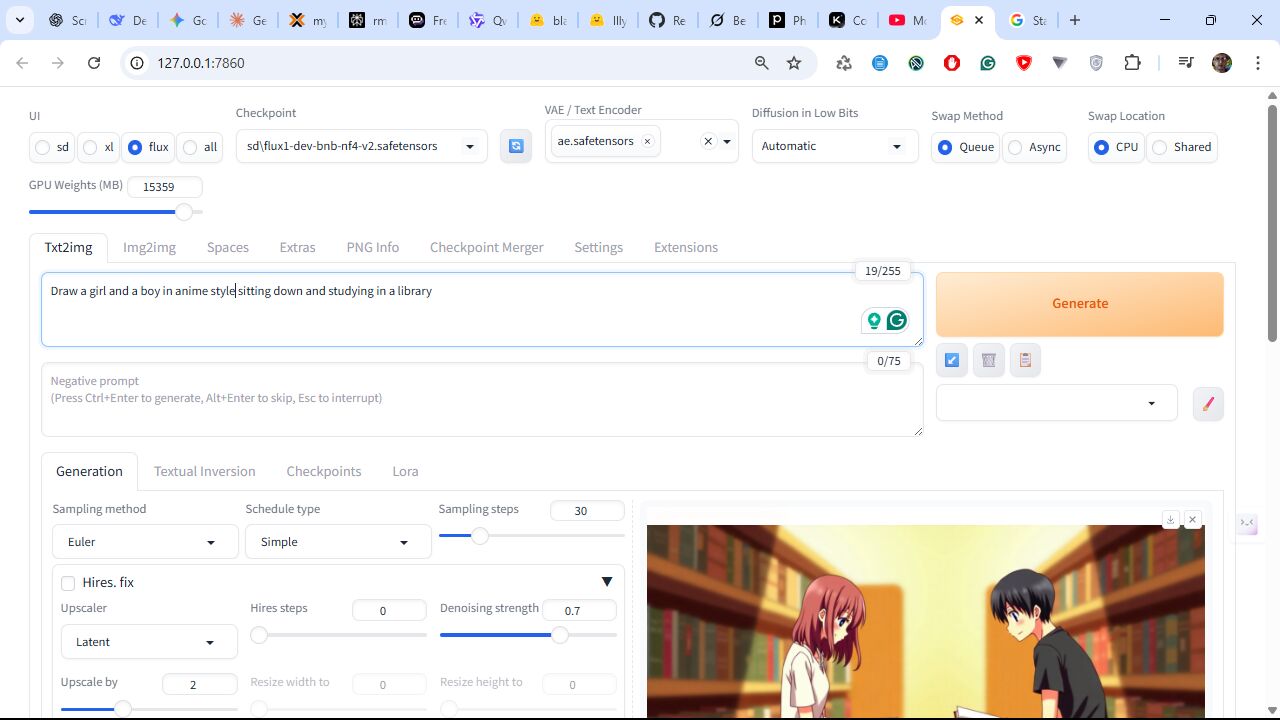
Dola.AI allows you to generate AI videos directly from a text prompt. Follow these steps:
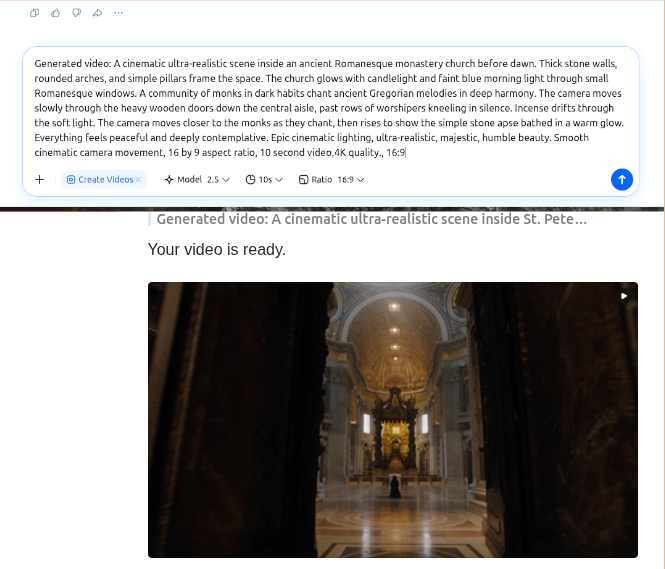
Google Flow is an AI-powered creative and filmmaking studio by Google that lets you generate, edit, and combine cinematic videos and images using text prompts.
Sometimes, you want to bring an existing picture to life without letting the AI completely redraw your work. Here is how to lock in your original image:
Switch to “Frames to Video” Mode. Instead of dragging your image straight into the standard text box, you must lock it as the opening shot.
Look right above or inside the prompt bar and look for a toggle that says Ingredients and change it to Frames.
Click on Start Frame (or First Frame) and upload your picture. This tells the AI: “This exact image is second zero of my video. Do not invent a new one.” Use this exact image, don’t reinterpret it!
Match the Aspect Ratio. Ensure your video’s output ratio perfectly matches your source image (e.g., 16:9, 9:16, 1:1) to prevent cropping or distortion.
Change your Prompt Strategy.
When using a Start Frame, stop describing the characters in your prompt. If you type “Jesus saving Peter,” the AI will attempt to generate its own version of them over your image. Instead, only describe the environmental forces acting upon the scene. You are effectively telling the AI to freeze the people, but move the world.
֎ Prompt Example: Animate the environment only. Keep the two central figures perfectly static and faithful to the start frame. Heavy storm waves roll and crash violently in the background. Rain falls heavily across the scene, and dramatic lightning flashes illuminate the dark clouds. \
Upgrade the Model: Lighter, faster models have a weaker grasp on strict image adherence. In the model selector dropdown, ensure you are using the Quality or Omni model for maximum fidelity to your starting frame.
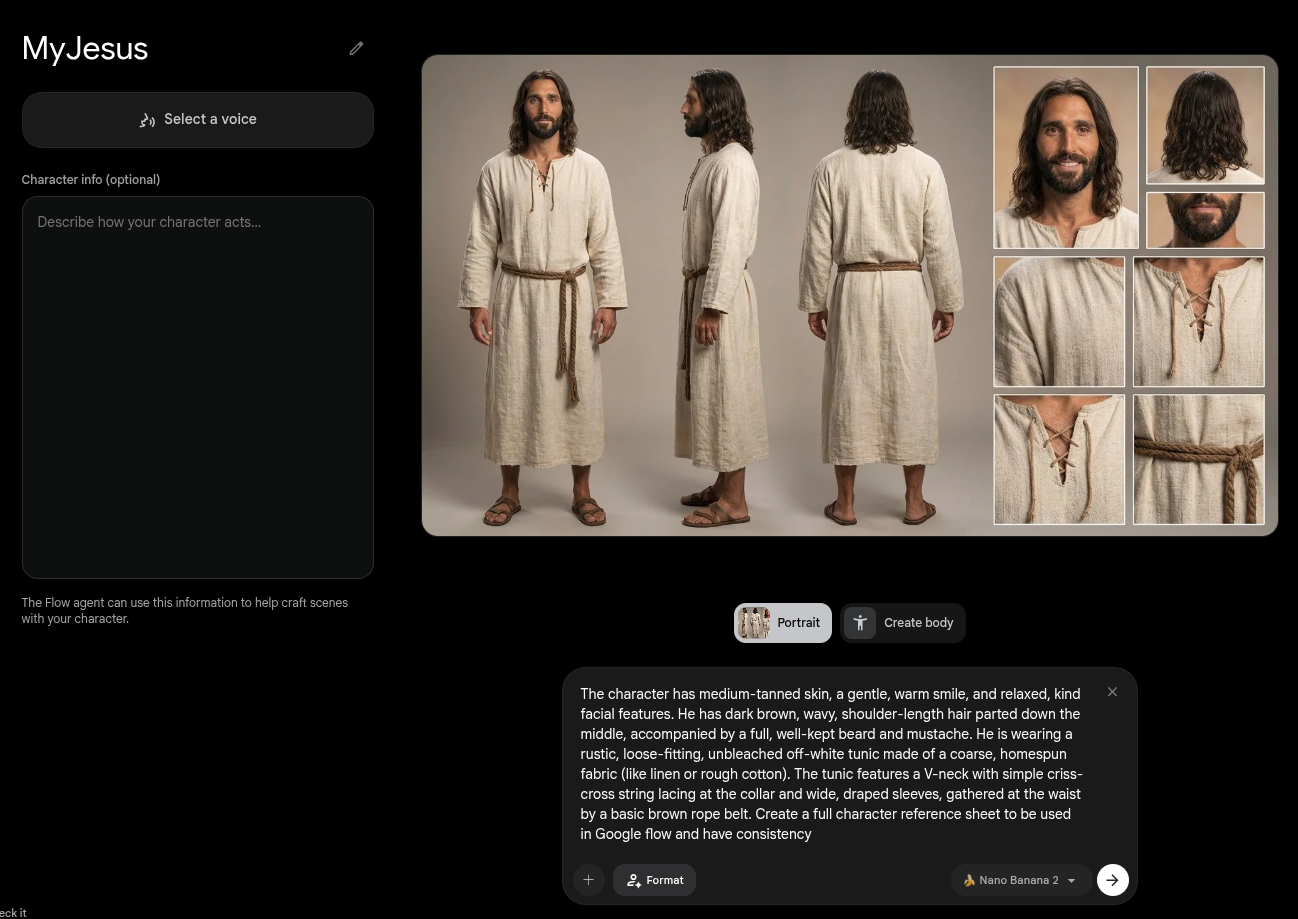
To use a consistent character across multiple projects and scenes, use the dedicated Characters tool rather than relying purely on text prompts.
Create the Profile: In the left-hand navigation menu, click on Characters, then select New Character.
Upload a Reference: If you already generated a perfect image, click Upload to bring in that photo. For the best results, use a front-facing image with a neutral expression and a plain background to act as your reference sheet.
Provide a Detailed Description: Pair your uploaded image with a highly specific breakdown of the character’s features and clothing.
Description Example: The character has medium-tanned skin, a gentle, warm smile, and relaxed, kind facial features. He has dark brown, wavy, shoulder-length hair parted down the middle, accompanied by a full, well-kept beard and mustache. He is wearing a rustic, loose-fitting, unbleached off-white tunic made of a coarse, homespun fabric (like linen or rough cotton). The tunic features a V-neck with simple criss-cross string lacing at the collar and wide, draped sleeves, gathered at the waist by a basic brown rope belt.
Generate Scenes Using the “@” Tool: When you are ready to animate, go to your main prompt box at the bottom of the screen. Type @ and select your character’s name from the popup menu to seamlessly insert them into the new scene.
To generate a video from your own picture on Meta’s Vibes.ai platform without losing facial accuracy, you must use the Image‑to‑Video pipeline, not the text‑prompt generator. This is because text prompts cause the model to reinterpret your face, clothing, and environment.
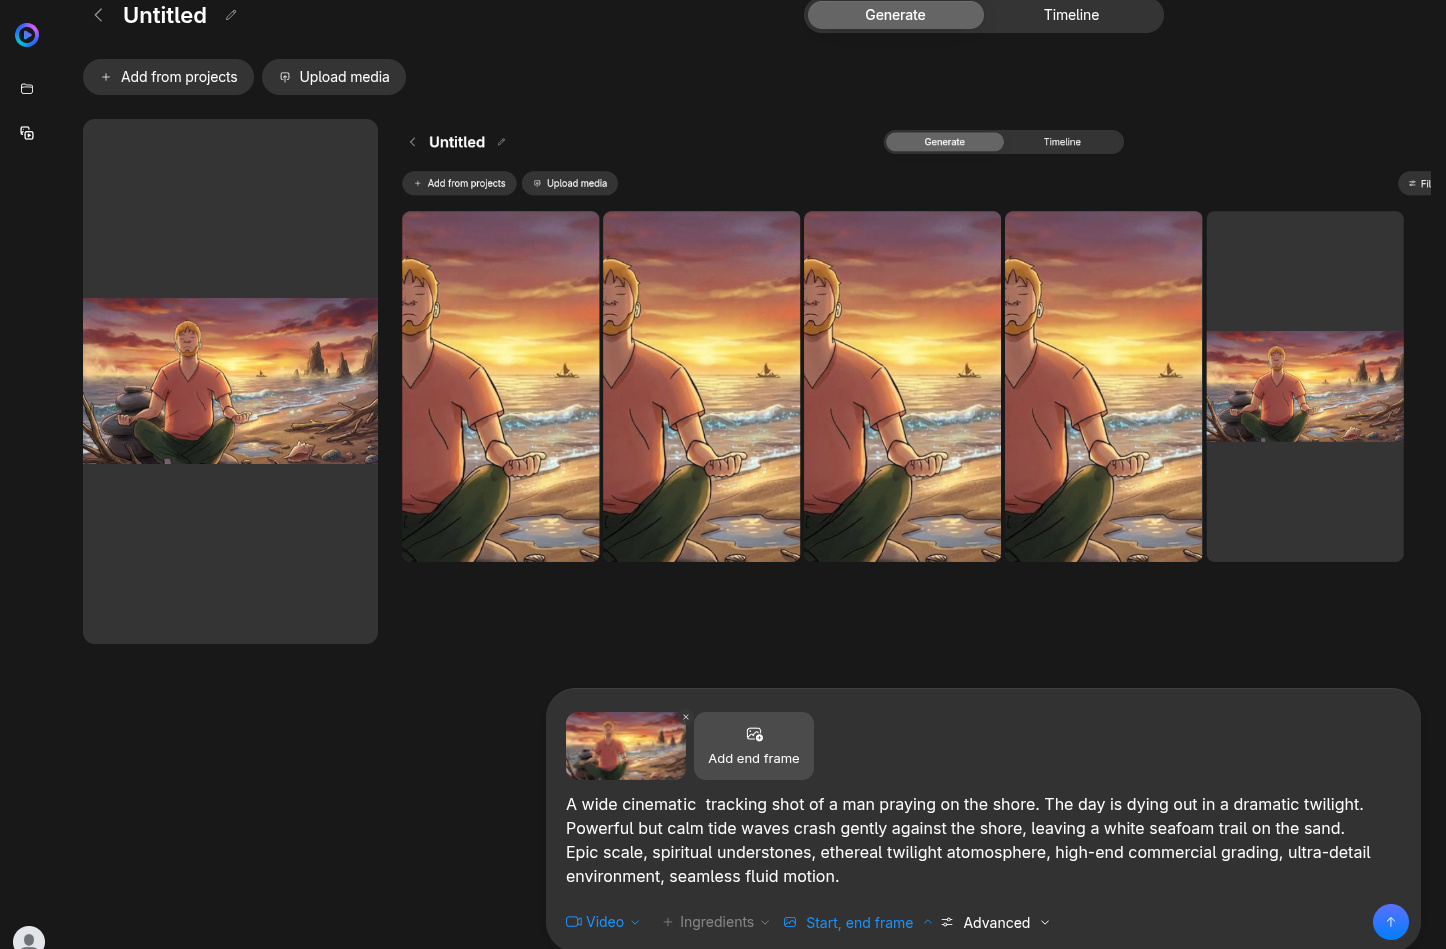
Video AI focuses on text-to-video, motion editing, and high-res outputs, but often struggles with consistency over long durations. Because they can mimic real people, most platforms include deepfake safeguards and identity‑protection filters.

JustToThePoint Copyright © 2011 - 2026 Anawim. ALL RIGHTS RESERVED. Bilingual e-books, articles, and videos to help your child and your entire family succeed, develop a healthy lifestyle, and have a lot of fun. Social Issues, Join us.
This website uses cookies to improve your navigation experience.
By continuing, you are consenting to our
use of cookies, in accordance with our Cookies Policy and
Website Terms and Conditions of use.